• Link to Xing
  • Link to LinkedIn
  • English English English en
  • Deutsch Deutsch German de
AT: +43 1 714 00 20 | DE: +49 69 348763610 | Mo-Fr 8am-5pm
Spirit in Projects
  • Training / ACADEMY
  • Blog
  • Innovation
  • Certifications
  • Consulting
  • About us
  • German
  • Click to open the search input field Click to open the search input field Search
  • Menu Menu

Requirements Specifications, Fixed Price, Fixed Deadline—and Please, Agile: Two Paradoxes in IT RFP Processes 

8. September 2026

Many IT tender begin in a very traditional way: requirements are gathered, coordinated, and then documented in a requirements specification or service catalog. Bidders prepare their proposals based on this foundation. 

During the hearing, the vendors present how they plan to organize the implementation. In my experience, many vendors present an agile implementation concept: with sprints, a backlog, and the usual Scrum rituals. In regular reviews or so-called “show-and-tell” sessions, they present what was implemented in the previous sprint. 
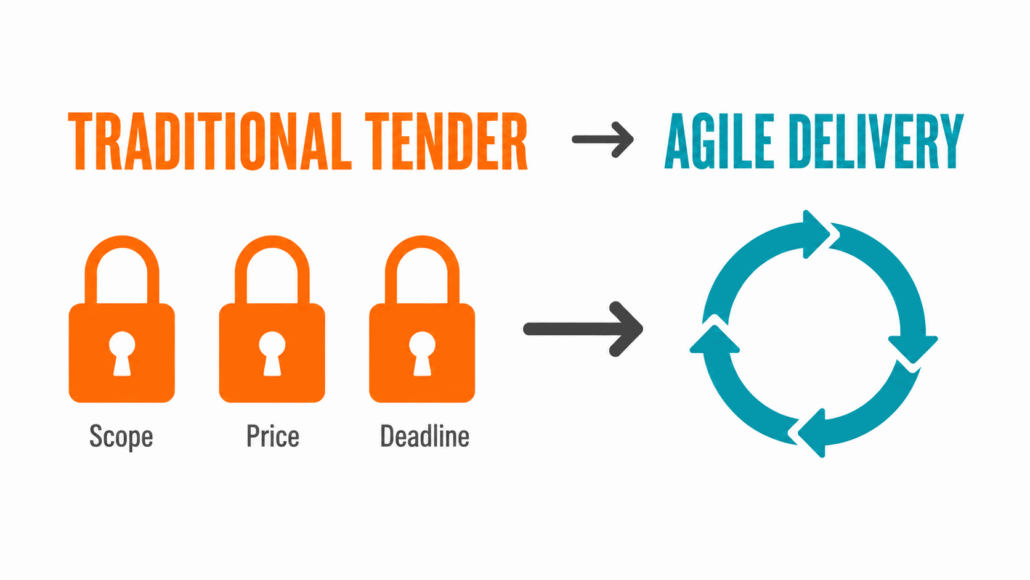
At first glance, this sounds like a sensible combination. The client receives a binding price and a defined scope of work. The vendor can still organize the implementation in an agile manner and deliver results on a regular basis. 

In practice, however, this gives rise to two paradoxes. 

The first concerns the relationship between new requests and the agreed-upon fixed price. The second goes even further: If the scope of work changes significantly during implementation, the question eventually arises as to whether the project being implemented is actually the one for which the competitive bidding took place. 

Paradox 1: The more the client learns, the more pressure is put on the fixed price 

During a show-and-tell session, features, processes, and user interfaces become clearly visible. This almost inevitably leads to new insights: 

  • “We could make this form simpler.” 
  • “We need some additional information here.” 
  • “If we automate this step, it would save a lot of time.” 
  • “Actually, we need one more interface.” 

That’s exactly what these meetings are for. The client is supposed to provide feedback, and the solution is supposed to improve as a result. 

However, a misunderstanding often arises. 

The client says, “We could still add that. After all, we’re working in an agile way.” 

The supplier adds the request to the backlog. The development team may implement it as early as the next sprint. Only later does it become clear that the requirement was not included in the agreed scope of work. A supplementary request follows. This comes as a surprise to the client: from their perspective, they simply provided feedback in an agile project. For the supplier, however, this constitutes an additional service that was not factored into the fixed price. 

Both sides have interpreted “agile” differently. 

The client expects flexibility. The supplier expects a limited scope of work despite the agile approach. 

A backlog is allowed to change. However, it is not a wish list with a price guarantee. 

If a new requirement is to be implemented without additional costs, another, roughly equivalent service would have to be omitted, for example. If, on the other hand, all previous requirements are to remain in place, the new request leads to more effort, more time, or additional costs. 

Agility does not negate these relationships. 
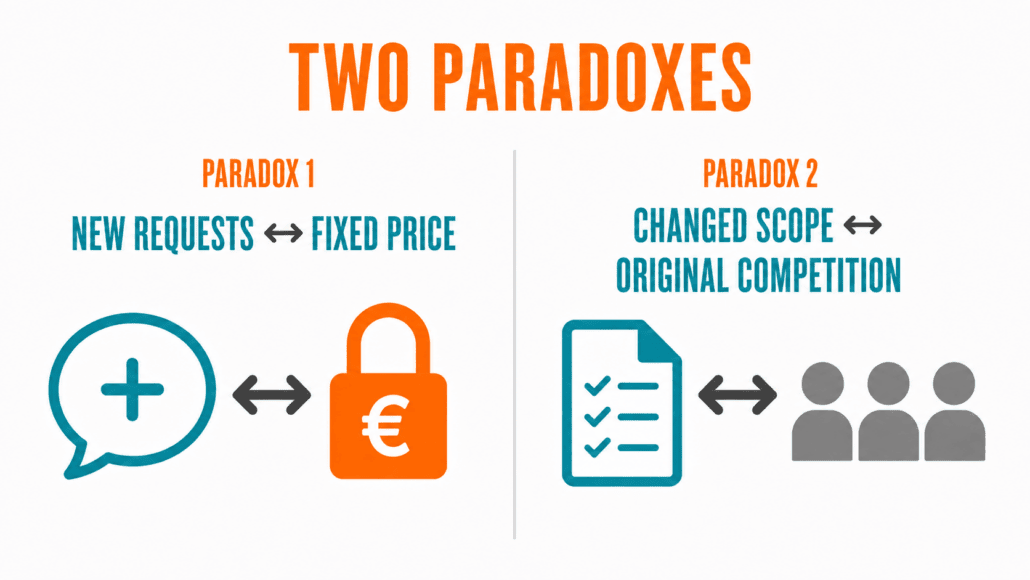
Paradox 2: The client is allowed to learn—but the competition must not change retroactively 

Even if the client and the supplier agree on the additional work, a second question remains. 

What happens if the scope of services changes so significantly during development that other companies would have participated in the original procurement process? 

Perhaps a bidder did not submit a proposal because the original specifications did not align with its core competencies. Perhaps another bidder could have offered a better concept or a lower price for the scope of services that emerged later. 

In that case, the change no longer affects only the existing contract. It affects the original competitive bidding process. 

The Austrian Federal Public Procurement Act specifically addresses this scenario: A contract amendment is considered substantial, in particular, if the amended terms would have sparked interest from other companies in the procurement process or made it possible to select a different bid. 

The further the backlog deviates from the tender specifications, the more questionable it becomes whether the contract for which the competitive bidding took place will actually be carried out. 

An agreement between the contracting authority and the supplier alone is then insufficient. If the change constitutes a material amendment to the contract, a new procurement procedure is generally required, unless a statutory exception applies. This is the second limitation of so-called agility: The client is allowed to learn during the project. However, the client may not place unlimited orders with the already-selected supplier for the results of this learning process. 

What does this mean in practice? 

New requests arising from a “show-and-tell” session should not automatically be interpreted as a work order. Before implementation, two checks are required: 

Contractually: Is the requirement already included, is it being exchanged for another service, or does it entail additional work? 

Under procurement law: Does the change fall within the scope of the contracted work, or might the modified contract have been of interest to other bidders as well? 

For each new requirement, there are thus four possibilities: 

  1. It is already covered by the agreed-upon scope of work. 
  2. It replaces a roughly equivalent requirement in the backlog. 
  3. It is commissioned as an additional service and is permissible under public procurement law. 
  4. It must be put out to bid separately or deferred. 

This decision-making logic should not be developed only during the project. It must already be included in the tender documents and the contract. 

A general statement such as “The backlog may be adjusted during the project” is not sufficient on its own. The tender documents should already clearly, precisely, and unambiguously specify which changes are possible, to what extent, and under what conditions. The overall nature of the contract must not be altered as a result. 

Conclusion 

Show-and-tell sessions aren’t the problem. They bring to light what wasn’t yet known when the requirements specification was drafted. That is precisely where their value lies. 

However, the insights gained need clear boundaries: 

Contractually: Is the requirement already included, will it be exchanged for another service, or will it create additional work?

From a procurement law perspective: Does the change remain within the scope of the tendered contract, or would the modified contract potentially have been attractive to other bidders?

What has been your experience? How are new requirements arising from sprint reviews or show-and-tell sessions handled in your fixed-price projects? 

Further Reading 

Status of legal basis: September 7, 2026. 

§ 365 BVergG 2018 – Contract Amendments During the Contract Term, current version 

Federal Public Procurement Act 2018 – complete consolidated version 

Article 72 – Contract modifications during the term of the contract, consolidated EU Public Procurement Directive 2014/24/EU of January 1, 2026 

Supreme Administrative Court (VwGH) decision of February 1, 2024, Ro 2020/04/0020 – Requirements for clear and precise contract amendment clauses 

This article provides a general overview and does not replace a legal review of the specific case in question. 
https://spiritinprojects.com/wp-content/uploads/2026/09/Team-Besprechung-.png 450 800 Wolfgang Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Wolfgang Hiermann2026-09-08 14:28:032026-09-08 14:31:50Requirements Specifications, Fixed Price, Fixed Deadline—and Please, Agile: Two Paradoxes in IT RFP Processes 

Agent-Ready: Why AI is the Least of Your Problems – and Infrastructure is the Biggest Challenge

20. August 2026

A company wants to introduce a customer service agent. The AI has been selected, the prompt is written, and initial tests with demo data look promising. Then comes the sobering reality: The agent cannot access the ticketing system because there’s no suitable API. The required customer data is scattered across systems that don’t communicate with each other, and some of the most up-to-date information exists only in Excel files on employees’ desktops. GDPR compliance for automated data processing is unresolved. And no one has defined what the agent is allowed to do when a customer wants to cancel their contract—or what it must never do.

The AI is ready to go. The organization is not.

This scenario is not an isolated case. In Part 1 of this series, we explored what agentic AI is and why it works technically: tools, planning, and memory—the three pillars that transform LLMs from chatbots into agents. But these three pillars require a foundation. And that foundation is missing in many companies.

What is Agent-Readiness?

Agent-Readiness describes the degree to which a company is technically and organizationally prepared to enable AI agents to work productively.

The analogy is clear: You wouldn’t onboard a new employee without providing them with a laptop, system access, a job description, and a point of contact. With AI agents, most companies do exactly that—they assume the AI’s capabilities and overlook the operational conditions.

The six dimensions of Agent-Readiness:

1. Tool Infrastructure → Can the agent act at all?

2. Data Accessibility → Can the agent access the right data?

3. Access Control → Is the agent permitted to do what it’s supposed to do?

4. Observability → Do we know what the agent is doing?

5. Accountability → Who is responsible if something goes wrong?

6. Team & Processes → Who builds, maintains, and improves the agent?

None of these dimensions are optional. Each can become a bottleneck that renders a theoretically powerful agent practically useless.

Dimension 1: Tool Infrastructure – Can the Agent Act at All?

Agents act through tools (function calling). Without tools, an agent is just a chatbot. But tools don’t exist by default—they must be built, documented, and deployed.

APIs as the Lifeline

Agents interact with systems via APIs. This isn’t new—but the quality of the API landscape determines whether an agent can function or not.

Agent-ReadyNot Agent-Ready
RESTful APIs with clear documentationNo APIs, only manual interfaces
Consistent authenticationDifferent authentication methods per system
Versioned APIs with backward compatibilityUndocumented changes, breaking changes
Structured error messagesCryptic errors or silent failures

Question for companies: How many internal systems have a machine-readable API?
If the answer is “half” or “less,” the agent can’t complete half the tasks—and will fail entirely when tasks require multiple systems to interact.

Tool Descriptions: The Human-Machine Interface

The AI selects tools based on natural language descriptions. Precise descriptions are critical—vague ones lead to incorrect tool calls or tools being ignored altogether. Parameters must be clearly defined: which values are expected, which are mandatory, and what formats are valid. Error cases must also be described so the LLM knows how to respond when a call fails.

Example:

❌ Poor tool description:

Name: search_customer

Description: Searches for customers

Parameter: query (string)

✅ Good tool description:

Name: search_customer

Description: Searches for a customer by name, email, or customer number.

Returns customer data including contract status and last interaction.

Use this when you need specific customer details.

Parameters:

– search_term (string, required): Name, email, or 8-digit customer number

– field_type (string, optional): “name”, “email”, or “customer_number” – improves search accuracy

Errors:

– “no_match”: No customer found. Ask the user for more details.

– “multiple_matches”: Multiple customers match. List the results and ask for clarification.

The difference isn’t cosmetic—it’s functional. With the first description, the AI might pass incorrect parameters, fail to handle errors, and guess when faced with ambiguity. With the second, it operates precisely, proactively, and resiliently.

Tool design for agents is a new craft: a blend of API design and UX design—except the user is an AI.

Dimension 2: Data Accessibility – Can the Agent Access the Right Data?

The smartest agent is useless if the data it needs is trapped in silos it can’t reach.

Common Data Barriers

BarrierImpact on the Agent
Data stored in Excel files on network drivesAgent can’t access it—no API available
Customer data spread across three systemsAgent can’t provide a unified answer
Documents as scanned PDFsAgent can’t read the text directly
Legacy systems without APIsAgent can only access them indirectly
Poor data quality (duplicates, inconsistencies)Agent works with incorrect data → unreliable results

What Agent-Readiness means here:

Data must be machine-readable and accessible. This sounds obvious, but in many companies, it’s the biggest bottleneck.

RAG (Retrieval-Augmented Generation) can bridge the gap for unstructured data (documents, manuals, wikis)—but only if: A functional vector database exists, Documents are current and well-structured, Metadata is available.

Data quality is agent quality. An agent working with outdated or contradictory data will produce outdated or contradictory results. Data maintenance isn’t made obsolete by agents—it becomes more important.

If a human takes 10 minutes to find a piece of information, how long does the agent take? If the answer is “longer” or “never,” the problem isn’t the agent.

Dimension 3: Access Control – Is the Agent Permitted to Do What It’s Supposed to Do?

Agents need access—but not to everything, and not with admin-level permissions. The principle of least privilege applies especially to them.

Permission Models for Agents

Right TypeWrongRight
Data accessAgent has access to all customer dataAgent sees only data relevant to the task
ActionsAgent can send emails to anyoneAgent uses only predefined distribution lists
System accessAgent has admin rights in the CRMAgent has a dedicated service account with restricted permissions
External APIsAgent can call any external APIAgent uses only approved, vetted APIs

Service Accounts for Agents

Agents should have their own identities—not those of human employees. This enables:

  • Auditing: Every action is traceable to the agent.
  • Permission scoping: The agent gets only the rights it needs for its task.
  • Deactivation: The agent can be shut down without affecting human users.
  • GDPR clarity: It’s obvious that a machine is accessing data.

Human-in-the-Loop as a Business Requirement

Not every action should be autonomous. The decision about which actions are autonomous and which require human approval is a business requirement—not a technical one.

ActionAutonomous?Reasoning
Retrieve customer data✅ YesRead-only access, low risk
Send standard email✅ YesPredefined templates, vetted
Process customer refund❌ NoFinancial impact
Change contract terms❌ NoLegal relevance
Escalate incident to support✅ YesTime-critical, clear process

This classification can’t be made by a tech team alone. It requires input from the business to define: Where is the risk acceptable? Where do we need human oversight? What happens if the agent operates in a gray area?

Dimension 4: Observability – Do We Know What the Agent Is Doing?

An agent may execute hundreds or even thousands of actions per day. Without traceability, this becomes a black-box operation—and that’s unacceptable.

Three Levels of Traceability

Level 1: Logging – What happened?
Every tool call is logged: which tool, what parameters, what result. Every reasoning step is stored: what did the agent consider before acting? Include timestamps, duration, and token usage per step.

Level 2: Monitoring – Is everything running normally?
Success rates of tool calls, average task duration, error rates by tool and task type, cost per task, escalation rate (how often human intervention is needed). Signal: If a tool suddenly fails more often, it’s a red flag.

Level 3: Auditing – Why did something happen?
Complete decision chains for every task. Traceability: Which input led to which action? Comparison: Did the agent solve the task? Does the result meet expectations?

What Good Agent Logging Looks Like

The difference between:

“The agent sent an email.”

And:

“On May 15, 2026, at 14:32, the agent sent an email to kunde@example.com with the subject ‘Your inquiry about order #4821’—because in Step 3 of the ReAct cycle, the load_order tool returned a status of ‘in progress,’ and the agent decided the customer needed to be notified.”

This level of detail is what makes auditing meaningful. Without it, the agent remains a black box—and black boxes have no place in production systems.

Dimension 5: Accountability – Who Is Responsible If Something Goes Wrong?

Agents make decisions and take actions. When something goes wrong, who is accountable? The answer is clearer than many think—and more uncomfortable than many hope.

The Three-Layer Model

Layer 1: The Model Provider (OpenAI, Anthropic, Google) is responsible for the quality and safety of the base model. However, model providers don’t know your company’s context. They don’t guarantee correct behavior in every application.

Layer 2: The Platform Team is responsible for tool design, guardrails, permissions, and monitoring. This is the bridge between what the model can do and what the agent is allowed to do in your company’s context.

Layer 3: The Business Domain is responsible for defining the task, approving actions, and validating results. The model delivers; the business decides.

The Uncomfortable Truth

An agent is not an autonomous actor. It’s a tool built, configured, and monitored by humans. Accountability always lies with the people who deploy it—not the AI.

Regulatory clarity confirms this:

The EU AI Act defines responsibilities for AI system deployment. The agent has no legal personality—the liability remains with the company. Companies that don’t document a clear strategy for agent deployment today will face compliance headaches tomorrow.

Dimension 6: Team & Processes – Who Builds, Maintains, and Improves the Agent?

Agents aren’t a one-time development project. They require continuous care, improvement, and adaptation. Most companies drastically underestimate this effort.

Three Roles Every Agent Project Needs

RoleResponsibilitiesTypical Profile
Agent DeveloperBuilds the agent, writes prompts, integrates toolsSoftware engineer with LLM experience
Agent OperatorMonitors operations, analyzes logs, intervenes when errors occurIT operations with AI understanding
Domain ExpertDefines tasks, evaluates results, provides domain knowledgeBusiness domain expert familiar with the process

Most common mistake: Developers build an agent without deep understanding of the business process. The result works technically but fails in practice. Collaboration between developers and domain experts is critical—and it takes time that’s often missing from project plans.

Processes That Must Be Established

Agent Lifecycle Management: From definition to development, testing, staging, deployment, and monitoring—agents need structured processes like any other software product.

Prompt Review: Prompts are code. They must be versioned, tested, and reviewed. A changed prompt can radically alter an agent’s behavior—for better or worse.

Tool Review: Every new tool changes the agent’s capabilities. New tools must be vetted: What could go wrong? What guardrails are needed? How does the agent respond to unexpected behavior?

Regular Evaluation: Agent performance evolves due to model updates, changing data, or new requirements. Regular testing with real-world tasks is not optional.

The Agent-Readiness Check: A Pragmatic Self-Assessment

Dimension✅ Agent-Ready⚠️ On the Way❌ Not Ready
Tool InfrastructureMost systems have well-documented APIsSome APIs exist but are poorly documentedMost systems lack APIs entirely
Data AccessibilityData is structured and machine-accessibleSome data is accessible; others are siloedData trapped in Excel, scanned PDFs, or legacy systems
Access ControlService accounts with least privilege in placePermission models exist but not for agentsShared admin accounts
ObservabilityFull logging and monitoring of agent actionsLogging exists but lacks agent-specific analysisNo systematic logging
AccountabilityRoles and responsibilities clearly definedPoints of contact exist but no formal processesNo explicit accountability
Team & ProcessesDedicated team with structured processesSome staff involved, but as a side taskNo personnel assigned

Rule of Thumb: If fewer than three dimensions are rated “✅ Agent-Ready,” focus first on infrastructure—not the agent. An agent built on weak foundations will fail. But investments in infrastructure pay off beyond agents, benefiting the entire digital transformation.

Outlook: Agent-Readiness Is a Maturity Level, Not a Destination

Agent-Readiness isn’t a one-time achievement. It’s a gradual maturity that evolves over time.

The good news: Every improvement to infrastructure benefits not just the agent, but the entire company. Better APIs, accessible data, clearer permissions—these are investments that pay off even without an agent.


Last Updated: May 2026

https://spiritinprojects.com/wp-content/uploads/2026/08/circuit-board-close-up-with-diff.jpg 450 800 Karl Schott https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Karl Schott2026-08-20 13:38:152026-08-31 17:56:49Agent-Ready: Why AI is the Least of Your Problems – and Infrastructure is the Biggest Challenge

New Micro-Certifications: Understanding AI—Compact and Practical

18. August 2026

Artificial intelligence has long been a part of everyday work life, but hardly anyone truly understands it fully. This is exactly where Spirit in Projects’ new micro-certifications (Micro Certs) come in: concise AI training with practical AI knowledge, presented in easy-to-digest chapters, supplemented by mini-quizzes, and culminating in a digital badge that you can even proudly share on LinkedIn.


What’s behind the Micro Certs?


A Micro Cert is a short, focused online training course: a self-contained learning module that you can work through at your own pace in 30 to 60 minutes. Micro Certs complement our traditional training offerings by providing a particularly quick way to get started and are ideal for anyone who wants to dive into a new topic without prior knowledge, without sacrificing depth of expertise.


Currently, there are two AI-focused Micro Certs to choose from:

1. SIP EU AI Act Ready Micro Cert

The ideal introduction for anyone who wants to truly understand generative AI for the first time. In six compact chapters (approx. 30 minutes), the course covers topics such as:

  • What generative AI actually is and how it differs from a traditional search engine
  • How language models “think” and predict answers word for word
  • What AI is already good at today and where its limitations lie
  • The basics of precise prompting (prompt engineering for beginners)
    • Golden rules for safely using AI tools in everyday life
  • A legal overview: risk classes and obligations under the EU AI Act
    At the end of each chapter, there’s a short knowledge quiz with immediate feedback—instead of flipping through thick manuals, you’ll learn directly through hands-on practice. Anyone who completes all 38 learning steps will receive a silver badge valid for six months.

2. SIP AI Literacy Micro Cert

If you’d like to dive deeper, you’ll find a much more comprehensive course here (approx. 60 minutes, 79 learning steps) with ten chapters: ranging from the AI landscape to machine learning, advanced prompt techniques, RAG, AI agents, and the responsible use of AI in business. The EU AI Act and typical risks in continuous operation, such as model drift, are also covered.
What makes this course special is that it concludes with a final exam. Those who pass it successfully will receive the coveted Gold Badge, valid for twelve months. This course also serves as an excellent foundation for training employees in accordance with the legal requirements of the EU AI Act (particularly Article 4).

Learn in small steps with immediate feedback

What both Micro-Certs have in common is their instructional structure:

  • Easy-to-understand chapters: Each topic is broken down into manageable chunks, explained clearly, and presented without unnecessary technical jargon.
  • Mini-quizzes between chapters: Instead of testing everything at once at the end, knowledge is reviewed in a fun way right after each chapter. This helps you retain what you’ve learned better.
  • Final exam (for the AI Literacy Micro Cert): For anyone who wants to demonstrate their knowledge comprehensively one more time.
  • Instant access and self-paced learning: The courses are entirely online, can be started at any time, and can be flexibly incorporated into your own schedule.

The Digital Badge: More Than Just a Pretty Icon

At the end of every successfully completed micro-certification, you’ll receive a digital badge—personal proof that you’ve seriously engaged with the topic of AI. And this LinkedIn badge is something to be proud of:

  • Digital & Verifiable: Through a public verification page, anyone—such as an employer or client—can verify at any time that the badge is genuine.
  • Shareable directly on LinkedIn: With just one click, the badge appears on your LinkedIn profile, showcasing your AI expertise to the outside world.
  • Validity at a glance: Since AI knowledge evolves rapidly, each badge is valid for a limited time, ensuring your certification always remains up to date.
  • Silver or Gold: Silver is awarded for successfully completing a Micro Cert, while Gold is awarded for Micro Certs that include an additional final exam.

Who is this for?

Whether you’re just starting your career, an experienced professional, or a manager: The Micro Certs are deliberately designed not to require any prior knowledge and are aimed at anyone who is increasingly working with AI tools in their day-to-day work but has never found the time for in-depth training. Especially for companies that need EU AI Act training for their employees, the AI Literacy Micro Cert offers a particularly practical introductory course on AI with a certifiable outcome.

Conclusion

The new Micro Certifications demonstrate that AI training doesn’t have to be time-consuming or dry. Short chapters, interactive quizzes, an optional final exam, and a digital, LinkedIn-compatible badge make getting started with AI easier than ever before.

👉 More information and registration: training.spiritinprojects.com/de/microcerts

https://spiritinprojects.com/wp-content/uploads/2026/08/microCerts800x450.jpg 450 800 Stefan Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Stefan Hiermann2026-08-18 14:02:142026-08-19 13:32:24New Micro-Certifications: Understanding AI—Compact and Practical

Without a cost-benefit analysis, every IT procurement is flying blind

10. August 2026

In larger IT projects, we repeatedly observe the same sequence of events: workshops are organized, requirements are gathered, specifications are drafted, and sometimes potential vendor solutions are already being reviewed. Technologies, functionalities, and budgets are discussed in detail.

Yet one crucial question is often raised far too late:


Is this investment even worthwhile?

This question, however, determines whether a project will ultimately succeed or whether, despite implementing a modern solution, the expected benefits fail to materialize.

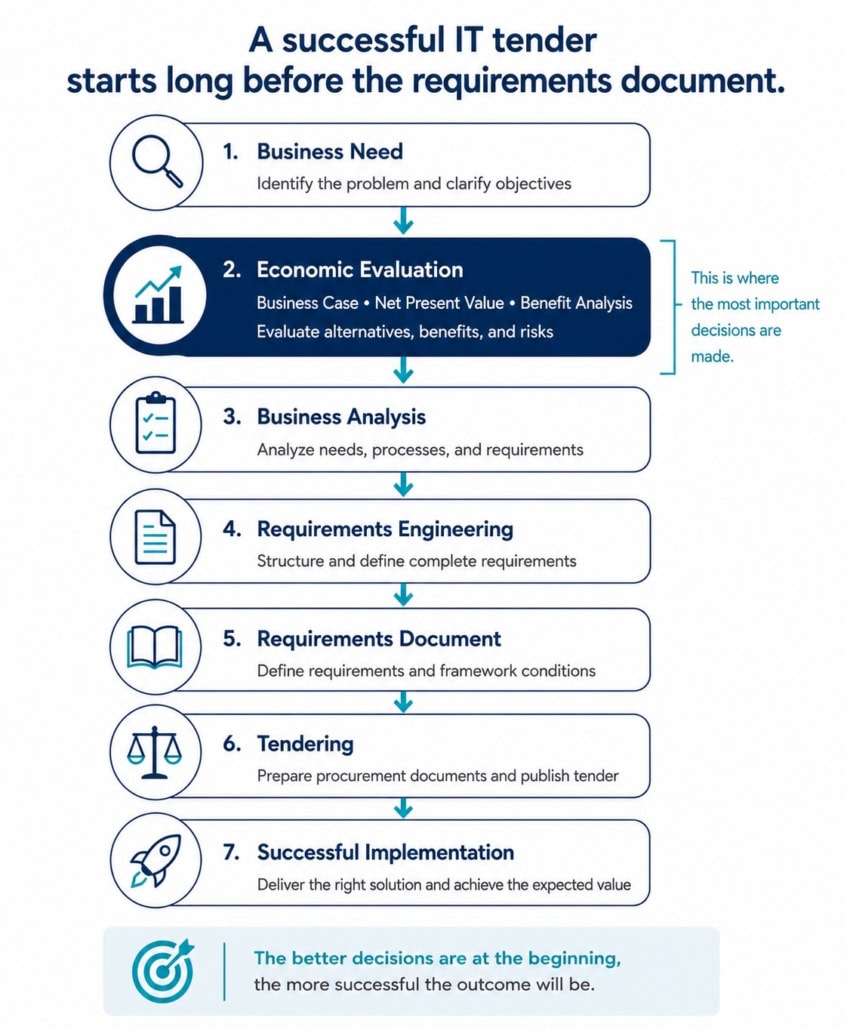
From our perspective, a successful IT procurement process does not begin with a specification sheet. It begins with a thorough cost-benefit analysis.

More than just a cost comparison

When people talk about cost-effectiveness, many initially think of a simple comparison of acquisition, operating, or licensing costs. But this is far too narrow. The cheapest solution is not automatically the most cost-effective.

Perspectives to consider when making investment decisions

A professional cost-benefit analysis addresses questions such as:

  • What problem is actually supposed to be solved?
  • What alternatives are available?
  • Which solution delivers the greatest long-term benefit?
  • What risks exist?
  • What impact will the investment have on processes, employees, and customers?

Only when these questions are answered can it be determined which solution is truly the most cost-effective.

Good decisions consider more than just numbers

Of course, investment and operating costs play an important role. Equally important, however, are the impacts that cannot be directly expressed in euros:

  • How significantly will process quality improve?
  • How much time will be saved in the future?
  • Will employee satisfaction increase?
  • Will service for our users and customers improve?

These factors often decide whether an IT investment achieves its desired success.
Those who focus exclusively on acquisition costs are only evaluating a small part of the actual cost-effectiveness.

Why a cost-benefit analysis is more relevant than ever today

7 Key Points That Make an IT Tender a Success

Various methods have become established for preparing investment decisions. They illuminate different aspects of cost-effectiveness and complement each other meaningfully.

The net present value method evaluates all monetary impacts of an investment over its entire lifecycle. Development, implementation, and operating costs are considered alongside savings and risks. The goal is to objectively assess the long-term economic benefit of an investment.

This analysis is supplemented by a utility value analysis, which evaluates factors critical to project success that cannot be reasonably expressed in euros. These include, for example, the strategic importance of a measure, quality improvements, shorter throughput times, better decision-making foundations, or benefits for citizens, businesses, and employees.

Another established approach is the business case. It expands the cost-benefit analysis by asking why an investment should be made at all. In addition to costs and benefits, it also considers strategic goals, alternatives, risks, and the expected added value for the organization.

After all, an investment may be economically viable but offer little strategic benefit. Conversely, a measure may be meaningful despite an initially negative net present value if it is of central strategic importance to the organization or delivers significant qualitative improvements. This is precisely why both monetary and qualitative aspects of an investment decision should be considered.

The greatest savings opportunities arise before the procurement process


Our experience from numerous IT projects shows that the greatest potential for savings rarely emerges during or after implementation.
They arise in the preparation phase.
A thorough cost-benefit analysis provides clarity on goals, alternatives, and risks. It prevents solutions (systems) from being procured that no one will need later. It helps define actual requirements accurately and creates a comprehensible basis for management and budget decisions.

This not only improves the quality of the specification sheet but also significantly reduces subsequent changes, addenda, and discussions during implementation.

The cost-benefit analysis is not a document—it’s a decision-making tool


Unfortunately, in many projects, the cost-benefit analysis is still seen as a tedious mandatory document created just before approval or procurement. Far too often, a decision is made first—and then an attempt is made to justify it economically.

Yet it should be exactly the opposite. The cost-benefit analysis should be the starting point for every major IT investment.
Not to justify an already-made decision, but to enable the best possible decision to be made in the first place.

How we support our customers

This is exactly where we assist our customers.
spirit in projects GmbH supports public sector clients and businesses in the strategic preparation phase of IT projects. Together, we analyze the need for action, compare solution alternatives, conduct cost-benefit analyses, perform utility value analyses, and develop robust specifications and procurement documents from this foundation.

Our goal is not just a successful procurement process. Our goal is to ensure that the right solution is procured.

Conclusion

A procurement process determines who receives the contract.
A cost-benefit analysis determines whether the right solution is even procured at all.

Skipping this step risks poor decisions, unnecessary costs, and projects whose expected benefits are never fully realized.
Therefore, every major IT investment should begin with a thorough cost-benefit analysis—not as a mandatory exercise at the end, but as the foundation for making a good decision.

https://spiritinprojects.com/wp-content/uploads/2026/08/Blog-Wahrscheinlichkeitsbetrachtung.jpg 450 800 Wolfgang Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Wolfgang Hiermann2026-08-10 13:22:332026-08-10 13:20:20Without a cost-benefit analysis, every IT procurement is flying blind

Agile Projects Aren’t Faster – And That’s Exactly Why Agility Needs Better Requirements Engineering

23. July 2026

Many companies today work with Scrum. Yet their Product Backlogs are overloaded, User Stories aren’t completed in a Sprint and regularly roll over into the next one. The team works from Sprint to Sprint—but the mountain of open requirements barely shrinks.

The introduction of Scrum was often justified with a clear goal: “We want to get faster.”
This is a sentence I’ve heard for years in nearly every company. Agile methods are seen as synonymous with speed, flexibility, and quick results.

But this is where the misunderstanding begins.

Speed Was Never the Real Goal

The original idea behind the Agile Manifesto wasn’t to complete projects as quickly as possible.
Instead, it aimed to prevent teams from spending months or years working on solutions that ultimately miss the customer’s needs.Rather than defining all requirements upfront, development happens incrementally:

  • Requirements are refined
  • Software is implemented
  • Users provide feedback
  • Insights feed into the next iteration

This learning process increases the likelihood of building the right product. But it also inevitably leads to additional coordination and changes.

Agility replaces long planning phases with continuous learning.

agility is not about speed

What Studies Actually Show

Scientific research confirms this picture.
A frequently cited study by Serrador and Pinto, involving over 1,000 projects, shows that agile projects perform better in customer satisfaction and adaptability. However, there is no clear evidence that agile projects are completed faster overall.

Investigations into large agile organizations reveal a similar pattern. The larger the project, the more coordination, architectural work, and requirements management become necessary. As project size increases, structured processes don’t disappear—they become even more important.

The Biggest Misconception: Agility Replaces Requirements Engineering

In many companies, a dangerous fallacy has taken root in recent years:
“We’re working agile. So we don’t need classic Requirements Engineering anymore.”

In reality, Requirements Engineering happens every day in Scrum projects.
Every User Story must be:

  • Understood
  • Aligned
  • Prioritized
  • Described
  • Reviewed
  • Accepted

That’s Requirements Engineering.
Only the artifacts and timing differ.
Instead of one large specification document, requirements emerge continuously throughout the project.

The Product Owner Carries a Huge Responsibility Today

With Scrum, much of the responsibility for requirements shifted to the Product Owner. Yet this is where a common weakness appears.
Many Product Owners have excellent product knowledge and deep stakeholder insights. But the role now demands far more than prioritization and backlog maintenance.

Professional Requirements Engineering has become one of the most critical competencies for a successful Product Owner.
What they often lack are the methods of professional Requirements Engineering:

  • Stakeholder analysis
  • Conflict management
  • Business process analysis
  • Modeling complex workflows
  • Defining measurable acceptance criteria
  • Quality checking requirements
  • Traceability
  • Handling non-functional requirements

These skills are often assumed in Scrum but rarely developed systematically.

product owner - a key role

Good User Stories Don’t Happen by Accident

A common misconception is: “We just write User Stories.”
But good User Stories are the result of careful analysis.
If you don’t understand the real needs of users, you’re just packaging unclear requirements into smaller chunks.

The consequences are:

  • Questions during development
  • Different interpretations
  • Frequent rework
  • Technical debt
  • Unnecessary debates in every Sprint

Many teams experience exactly this—and then blame Scrum.

poor requirements cost time in every sprint

In truth, the problem often lies in missing foundational Requirements Engineering skills.
A Product Backlog doesn’t replace requirements analysis. It only documents the outcome.

Agile Projects Invest Differently – Not Less

Traditional projects invest a larger portion of effort upfront. Agile projects spread that effort across the entire timeline.
That’s why agile projects often appear to start faster. But in reality, analysis, alignment, and prioritization happen continuously.
The analytical effort doesn’t vanish. In many Scrum projects, it’s merely deferred.

Instead of thoroughly analyzing requirements before development, discussions happen during the Sprint. Developers ask questions, Product Owners make rushed decisions, and User Stories get revised. These are the very delays Scrum was meant to avoid.

Agility Needs Better Requirements Engineering

Especially because agile projects thrive on short decision cycles, professional Requirements Engineering becomes more important than ever.
A Product Owner shouldn’t just understand the product—they should master the methods that create good requirements.

These include:

  • Systematic stakeholder analysis
  • Facilitating conflicting interests
  • Process analysis
  • Clear modeling (possibly with UML)
  • Formulating verifiable requirements
  • Defining clear acceptance criteria
  • Prioritizing by business value
  • Continuous validation with users

These skills often determine whether an agile team works efficiently or gets bogged down in misunderstandings Sprint after Sprint.

agility needs requirements engineering

Conclusion

Agility doesn’t automatically make projects faster. It makes change easier. That’s a crucial distinction.
Those who equate agility solely with speed will inevitably be disappointed. But those who see it as a tool to reduce risk and learn faster will recognize its true value.

Professional Requirements Engineering hasn’t become obsolete in agile projects.
On the contrary:
The more agile a project is, the more important it becomes to deliver the right requirements at the right time and in the right quality.

Perhaps this is the most important lesson of the past twenty years of agility:
The most successful Scrum teams I know don’t spend less time on requirements—they spend more. The difference is that they do Requirements Engineering continuously and systematically before every Sprint. That’s why their backlogs stay manageable and their User Stories get completed within a Sprint.

https://spiritinprojects.com/wp-content/uploads/2026/07/agilitaet.jpg 450 800 Wolfgang Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Wolfgang Hiermann2026-07-23 09:21:412026-07-27 11:51:19Agile Projects Aren’t Faster – And That’s Exactly Why Agility Needs Better Requirements Engineering

Why Now Is the Right Time to Rethink Business Processes

20. July 2026

Cloud computing, AI, new licensing models, and regulatory requirements are fundamentally transforming the IT landscape. Those who view these changes purely from a technical perspective are missing out on enormous potential.

Few CIOs or IT leaders today would complain about a lack of challenges. Companies are migrating their applications to the cloud, exploring the use of artificial intelligence, and simultaneously adapting to new licensing models as well as regulatory requirements such as NIS2, DORA, or the EU AI Act. Added to this are rising license costs, a shortage of skilled workers, and the desire to finally make digitalization measurable.

In our projects, we repeatedly observe a similar pattern: the focus is initially on selecting the right technology. Which platform should be used going forward? Which systems need to be replaced? Which data needs to be migrated?

These questions are important. However, they often fall short. The real question is:
Do our current business processes still support our company’s goals?

Now is the perfect time to ask this question anew.

A New System Rarely Solves an Old Problem

When software is replaced or modernized, projects often focus on technical questions:

  • Which platform should we choose?
  • Which data needs to be migrated?
  • Which interfaces need to be adjusted?
  • When will the go-live occur?

From our experience, this often pushes the actual business processes into the background. A new system does not turn a bad process into a good one—it merely digitizes it. Those who adopt existing workflows unchanged usually inherit their weaknesses as well.

Historically Evolved Processes

Few business processes are developed once and then remain unchanged. They evolve over many years. New legal requirements, organizational changes, or technical constraints lead to processes being expanded step by step.

Each individual adjustment may make sense on its own. However, collectively, they often result in additional approvals, manual tasks, or media discontinuities whose original purpose has long since been forgotten.

This is precisely why a system change should not be seen as just an IT project. It offers the ideal opportunity to critically examine existing processes and assess their actual value.

The Real Driver Is Often Not Digitalization

Interestingly, many transformation projects today do not originate from a strategic decision. Instead, they are frequently triggered by external conditions, such as:

  • The end of support for existing software solutions,
  • Changes in manufacturers’ licensing models,
  • Regulatory requirements necessitating organizational adjustments, or
  • New technologies like AI opening up entirely new possibilities.

In our projects, we repeatedly see that technology is merely the trigger. The real need for change often lies in the business processes.

Process Analysis Is Not an End in Itself

We sometimes hear the phrase:
“We already know our processes.”
In practice, however, this is often not the case. Different departments have different ideas about the same process. Responsibilities are not clearly defined. Individual process steps exist only because they were once necessary years ago.

A structured process analysis creates transparency in such cases.

Unfortunately, process analysis is often confused with documentation. The goal is not to create as many BPMN diagrams as possible. Instead, a good process analysis answers fundamental questions:

  • What goal does the process pursue?
  • What benefit does it provide for customers and the company?
  • Which steps actually create value?
  • Where do waiting times or media discontinuities occur?
  • Which decisions could be automated?
  • What information is truly needed?
  • Which process steps exist only for historical reasons?

Only when these questions are answered can requirements for a future solution be meaningfully defined.

Good Processes Reduce More Than Just Costs

In many projects, discussions primarily revolve around license costs or implementation effort. Yet the greatest savings potential often lies elsewhere.

Optimized processes lead to shorter lead times, fewer manual tasks, reduced training requirements, and higher data quality. At the same time, individual customizations, interfaces, and subsequent operational efforts decrease.

Our experience shows that a well-founded process analysis often pays off even during the introduction of a new system.

Business Analysis Before Technology

From our perspective, digitalization does not begin with the selection of software. It begins with the company’s understanding of its own processes.

Only when processes, goals, and requirements are understood can it be determined:

  • Which functions are actually needed,
  • Which processes can be simplified,
  • Where automation makes sense, and
  • Which technology delivers the greatest added value.

In successful projects, technology follows the process—not the other way around.

Conclusion

Never before have companies faced so many technological changes at once. Cloud migrations, artificial intelligence, new licensing models, and regulatory requirements make IT investments unavoidable.

However, our experience from numerous digitalization projects shows that successful transformations do not begin with the selection of new software but with an understanding of one’s own business processes.

Those who use the current pressure for change to critically question and redesign processes not only lay the foundation for a successful system implementation. They also create the basis for a company that can more easily manage future technological changes.

https://spiritinprojects.com/wp-content/uploads/2026/07/Geschaeftsprozess-ueberdenken.jpg 450 800 Wolfgang Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Wolfgang Hiermann2026-07-20 12:55:122026-07-20 11:45:00Why Now Is the Right Time to Rethink Business Processes

The True Costs of Poor Requirements

22. June 2026

Why IT Projects Rarely Fail Due to Technology—But Often Due to Unclear Requirements

When an IT project fails, the blame is often placed on technology:

  • The software wasn’t mature enough.
  • The vendor delivered poorly or not at all.
  • The architecture was unsuitable for the problem.
  • The developers were overworked.

In reality, however, the real issues often arise much earlier—long before the first line of code is written. They emerge when projects are launched with unclear goals, conflicting expectations, and poorly defined requirements. The consequences usually only become visible months later—but then with full force.

The Most Expensive Mistakes Happen in the First Few Weeks

At the start of many projects, there is immense time pressure.
The budget is finally approved, the project can begin, and the business department—which has been waiting for a solution for months—naturally pushes for rapid implementation. This creates a strong temptation to shorten the analysis phase, especially since teams have already discussed the problems and desired features for a long time.

This is where the first major mistake often occurs:
A misunderstanding in a requirements workshop may cost just a few minutes. The same misunderstanding after go-live can cost hundreds of thousands of euros.

As software engineering pioneers Barry Boehm and Victor Basili demonstrated in the late 1970s, errors detected in later project phases are exponentially more expensive to fix than those caught during requirements analysis. In many cases, correction costs increase ten- to a hundredfold. They referred to this phenomenon as the “Cost Escalation Factor”.

Saving time on analysis rarely saves money—it merely shifts costs to later phases.

The Numbers Are Alarming

Poor requirements are not just a theoretical problem—they have real-world consequences. Numerous studies highlight this:

  • The Project Management Institute (PMI) identifies inadequate requirements management as a key reason why projects fail to meet their goals.
  • Research by the International Institute of Business Analysis (IIBA) and IAG Consulting found that poor requirements in large projects can lead to cost overruns in the millions.
  • A study by Bent Flyvbjerg and Alexander Budzier (University of Oxford), based on 1,471 IT projects, revealed that projects exceed their budgets by an average of 27%. Even more critically, one in six projects became a “black swan,” overshooting planned costs by 200% on average while also facing severe delays. The root causes were rarely technological but instead stemmed from unclear objectives, unrealistic assumptions, and inadequate requirements definition.

The Costliest Misconception: Confusing Features with Value

A common mistake is that organizations describe what features a system should have in great detail but fail to define what value it should deliver.

The result? Specifications that look impressive on paper but miss the actual business need. Users only realize during operation that the system doesn’t support their daily work.

Instead, the right questions should be asked:

  • What problem is being solved?
  • Which key performance indicators (KPIs) should improve?
  • How will success be measured?
  • What value justifies the investment?

Without answering these, the outcome is often a system that meets all requirements yet is still perceived as a failure—not because the software is bad, but because the expected value was never clearly defined.

Poor Requirements Trigger a Domino Effect

High costs from poor requirements are not just due to expensive late-stage changes. The real damage comes from:

  • Procuring the wrong solution
  • Project delays
  • Claim and change management
  • Budget overruns
  • Increased testing efforts
  • Low user adoption and productivity losses
  • Missed business goals
  • Additional operational and integration costs
  • Loss of trust in IT projects

These costs are difficult to quantify but often far exceed development expenses—and their impact can linger for years after go-live.

Why Requirements Management Is a Leadership Responsibility

Requirements engineering is often seen as an operational task. In reality, it is risk management in the context of investment decisions.

Good requirements provide transparency on:

  • Goals
  • Value
  • Scope
  • Risks
  • Priorities
  • Quality

They form the foundation for sound decision-making. The larger and more complex a project, the more critical this transparency becomes.

Conclusion

Most IT projects don’t fail due to a lack of skills or technology. They fail because different stakeholders have different understandings of what should be achieved—or because the value the system is supposed to deliver was never properly defined.

This is why requirements are far more than just documentation. They are the basis for Investment decisions, Tender processes, Architecture, Development, Testing and Operations.

Those who skip professional requirements management aren’t saving effort—they’re taking a gamble. A gamble that all parties share the same understanding of the project and its goals.

Experience shows: This bet is lost surprisingly often.

The costs of poor requirements rarely hit all at once. Instead, they accumulate through poor decisions, rework, delays, and missed value—often exceeding the original investment in professional requirements analysis many times over.

Sources & Further Reading

  • Project Management Institute (PMI): Pulse of the Profession
    https://www.pmi.org/learning/thought-leadership/pulse
  • Flyvbjerg, B.; Budzier, A. (2011): Why Your IT Project May Be Riskier Than You Think, Harvard Business Review
    https://hbr.org/2011/09/why-your-it-project-may-be-riskier-than-you-think
  • Boehm, B.; Basili, V. (2001): Software Defect Reduction Top 10 List, IEEE Computer
    https://www.cs.umd.edu/projects/SoftEng/ESEG/papers/82.78.pdf
  • Consortium for Information & Software Quality (CISQ): The Cost of Poor Software Quality in the US
    https://www.it-cisq.org/the-cost-of-poor-quality-software-in-the-us-a-2022-report/
  • IAG Consulting: Business Analysis Benchmark Report
    https://www.iag.biz/business-analysis-benchmark-2008/
https://spiritinprojects.com/wp-content/uploads/2026/06/Kosten-schlechter-Anforderungen_800x450.png 450 800 Wolfgang Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Wolfgang Hiermann2026-06-22 14:57:092026-06-22 14:56:47The True Costs of Poor Requirements

The 10 Most Common Mistakes in IT Tenders – and Why Many Projects Fail Before Publication

18. June 2026

The tender is published. The budget is approved. The first bidder questions arrive.
At this point, the project should be on solid ground.
Yet in reality, many IT projects are set on a problematic course months before the tender is even published—not because the providers are unsuitable or the technology fails, but because essential preparatory work was never carried out.
In our consulting practice, we repeatedly observe the same patterns. Most problems arise long before a single line of the requirements specification is written.

Mistake 1: The current situation was never truly analyzed

Often, only symptoms or assumed solutions are discussed, such as: “We need a modern solution”, “Users are dissatisfied” or “We should use AI.” These statements rarely describe the actual problem to be solved.

Before discussing new systems, the following must first be understood:
  • Which processes are affected?
  • Which stakeholders are involved?
  • Where are time losses occurring today?
  • What media discontinuities exist?
  • What data issues persist?

An analysis often reveals that the real problems are organizational in nature or can be resolved through adjustments to existing systems.

Mistake 2: The desired benefits were not defined

Many tenders detail what a system should be able to do and which functions are desired. Rarely, however, do they explain why the system is being procured in the first place—and this is precisely the critical question.

What goals should be achieved?
  • Faster processing times?
  • Fewer manual tasks?
  • Higher data quality?
  • Improved customer satisfaction?
  • Compliance with regulatory requirements?
  • Greater information security?

A clear distinction between performance objectives and usage objectives is essential. While performance objectives describe the functions and characteristics a solution should have, usage objectives define the actual benefits for the organization, such as shorter processing times, lower costs, or improved data quality.
A tender with 500 requirements is of little use if no one can articulate the concrete benefits the solution is expected to deliver.

Mistake 3: Requirements are collected instead of analyzed

Many organizations hold workshops to gather requirements, resulting in long wish lists.

Yet often, the following questions are not asked:
  • Why is this function needed?
  • What problem does this function solve?
  • What added value does it create?

Requirements engineering is not about collecting requirements—it’s about identifying, understanding, questioning, elaborating, and prioritizing the right requirements. Investing this time ensures not just a tender process, but the procurement of a sustainable, maintainable, and beneficial system.

Mistake 4: Business departments and IT work in isolation

The business department describes its wishes and needs. IT outlines technical constraints. A gap often forms between them. The consequences include contradictory requirements, unrealistic expectations, and misunderstandings among providers.
Successful tenders emerge from the collaborative work of business units, IT, data protection, information security, and other stakeholders.

Mistake 5: Processes are not considered

A new system often merely digitizes existing weaknesses.
If inefficient processes are transferred unchanged into a new system, no real added value is created.

Before issuing a tender, the following should always be examined:
  • Which processes should be supported?
  • Which process steps can be eliminated?
  • Where do automation potentials exist?

Mistake 6: Non-functional requirements are missing

Many tenders include hundreds of functional requirements. Yet a system that meets all desired functions but is slow, insecure, or unmaintainable is often perceived as a failure by users.

Key quality attributes to consider include:
  • Performance
  • Availability
  • Scalability
  • IT security
  • Data protection
  • Reliability
  • Maintainability

These aspects can determine the success or failure of a project, particularly in critical infrastructures and public institutions.

Mistake 7: The existing system landscape and future viability are insufficiently considered
The existing system landscape is often only inadequately examined.

The existing system landscape is often only inadequately examined.

New solutions rarely operate in isolation. They must integrate with existing application landscapes.
Those who fail to understand existing systems, interfaces, and data flows significantly underestimate effort, risks, and costs.


Future viability is not considered.
Another aspect is the rapid evolution of technology. Topics such as:

  • Artificial intelligence
  • Automation
  • Cloud strategies
  • API capabilities
  • Data integration
  • Future enterprise architecture

should already be addressed during the tender process.

Mistake 8: Operations are forgotten

Many tenders focus exclusively on implementation.
Yet the real costs often arise afterward:

  • Maintenance
  • Support
  • Operations
  • Further development
  • Training

A good tender considers the entire lifecycle of a solution.


Mistake 9: Evaluation criteria do not align with the project

Those who evaluate solely based on price often do not receive the most cost-effective solution.
Evaluation criteria should always support project goals and consider professional, technical, and organizational aspects.
The situation becomes particularly critical when criteria are defined but have little actual impact on scoring.

Mistake 10: Independent support is lacking

Tenders are not just procurement projects—they are transformation projects. Many organizations conduct IT tenders only once every few years, meaning they often lack experience with current methods, technologies, market developments, and the evaluation of complex solution concepts.
Independent support helps to:

  • Structure requirements,
  • Identify risks early,
  • Engage stakeholders,
  • Assess bidder concepts and potential solutions for feasibility, and
  • Prepare sound decisions.

Conclusion

Most failed IT projects do not fail due to technology. They fail because of unclear goals, insufficient analysis, and inadequate requirements.
Investing time in analysis before issuing a tender saves many times the cost, delays, and project risks later on.
The best tender is not the one with the most requirements, but the one with the clearest understanding of the actual problem and the intended benefits.
Successful tenders do not begin with a requirements specification, but with an understanding of the initial situation, goals, and expected benefits.

https://spiritinprojects.com/wp-content/uploads/2026/06/Bild-1-1-1.jpg 576 1024 Wolfgang Hiermann https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Wolfgang Hiermann2026-06-18 09:30:322026-06-18 09:30:14The 10 Most Common Mistakes in IT Tenders – and Why Many Projects Fail Before Publication

Agentic AI: Why AI Systems Can Now Act Autonomously – The Fundamental Concepts That Aren’t Explained Enough

21. May 2026

Monday morning. An AI receives the task: “Analyze all customer complaints from the past week, check if the most common issues appear in the system logs, and write a summary for management.” Two hours later, the report is ready—structured, complete, with source references from the ticketing system.

No human clicked, copied, or monitored anything.
This is Agentic AI—and many are amazed as if it were magic. It’s not magic. It’s three concrete capabilities that modern Large Language Models (LLMs) now possess. Understanding these fundamentals reveals why the current hype is technically justified—and where the limits lie.

What an LLM Really Is—and How It Relates to Agency

At its core, an LLM is a machine that, based on a vast training dataset, learns which word (or more precisely, which “token”) is most likely to follow in a given context. From this seemingly simple mechanism—given sufficient model size and training data—emergent abilities arise that no one explicitly programmed: reasoning, planning, reflection.

These are called emergent capabilities—properties that “appear” beyond a certain threshold without being directly trained.

What was missing until recently: hands. The model could think—but it couldn’t act.

The Three Pillars of Agentic AI

Agentic AI emerges when an LLM is equipped with three capabilities: tools, planning, and memory. None of these alone makes an agent. Together, they create a system that can autonomously solve multi-step tasks.

Pillar 1: Tools – The Agent’s Hands

Tool use (also called “function calling”) is the technical mechanism that transforms LLMs from chatbots into agents. The principle is surprisingly simple and can be broken down into three questions:

  1. How does the model know which tools are available?
  2. How does it select the right tool for a task?
  3. How does it use the tool correctly?

Early tools were simple, like internet search via search engines. But as LLMs proved adept at writing code, it became clear they could also manipulate files and other data sources. The combination has proven more powerful than initially expected.

The Menu: How the LLM Knows Its Tools

At the start of a task, the LLM is provided with a list of available tools—not as a technical API documentation, but as readable descriptions in natural language. Each tool gets a name, an explanation of what it’s for, and a description of the expected parameters. Conceptually, it might look like this:

TOOL NAMEDESCRIPTIONPARAMETERS
lade_ticketsLoads support tickets from the CRM systemTime period, type (complaint/request), status
search_logsSearches system logs for a keywordSearch term, time period, log level
send_emailSends an email via the company’s mailing listRecipient, subject, content
create_documentFormats and saves a documentTitle, content, storage location

The LLM reads these descriptions like a menu—and decides, based on the task and tool descriptions, whether a tool fits the current situation. The quality of these descriptions is critical: a vaguely described tool will either be misused or ignored entirely.

The Decision: How the LLM Chooses the Right Tool

The model doesn’t select tools through separate logic or a rule system—it’s pure language understanding. The LLM simultaneously reads the task and the tool descriptions, then writes a plan to decide which tool best fits the situation. It considers:

  • Does the tool match the task? → “I need current data” → No reliance on training knowledge, but a tool call.
  • What parameters does the tool require? → The model extracts needed values from the task description or prior context.
  • Is the tool even useful right now? → The model may decide not to call a tool and respond directly if it already has all necessary information.

Important: The model can select the right tool from a list of ten or twenty—but it only chooses from the tools explicitly provided to it.

The Execution: How the LLM Activates a Tool

When the model wants to use a tool, it doesn’t return a response in natural language. Instead, it generates a structured request: the tool name and parameters in a machine-readable format. Conceptually:

Tool = load_tickets

Parameters = Time period = “last 7 days”

Type = “complaint”

Status = “open”

The surrounding application receives this call, executes it (e.g., queries the CRM system), and returns the result to the LLM. The model processes the result and decides:

  • Is this enough?
  • Do I need another tool?
  • Can I now complete the task?

This cycle—task → tool call → result → next decision—can repeat multiple times until the task is fully resolved.

A critical detail for security-conscious readers: The LLM does not execute tools itself. It writes a structured call request—the surrounding application executes it, deciding whether and how to fulfill the request. This isn’t a technical limitation but a deliberate architecture: it ensures full control over which actions are possible, which systems are accessible, and what permissions are used.

Pillar 2: Planning – The Agent’s Thinking

Tool use alone isn’t enough. A complex task consists of multiple steps that must be executed in the correct order, depend on each other, and influence one another. That’s where planning comes in.

Modern LLMs can improve measurably on complex tasks through a simple technique: explicit “step-by-step thinking” (also called Chain of Thought). Instead of just asking for the answer, the model is asked for the path to the answer. This sounds trivial but, in benchmarks, doubles the quality for multi-step problems.

The most important architectural pattern for agents is the ReAct pattern (Reasoning + Acting). It describes a thought-action-observation loop:

Thought: What do I need next?

Action: [Tool call with parameters]

Observation: [Result of the tool]

Thought: What does this result mean? What’s the next step?

Thought: What do I need next?

Action: [Tool call with parameters]

Observation: [Result of the tool]

Thought: What does this result mean? What’s the next step?

A concrete example from our opening scenario:

Thought: I need the customer complaints from the past week.

Action: [Tool: load_tickets, Time period: last 7 days, Type: complaint]

Observation: [247 tickets, most common category: “Login issues” (38%)]

Thought: Login issues are the most common category.

I’ll check if there are entries in the system logs.

Action: [Tool: search_logs, Search term: “authentication error”, Time period: 7 days]

Observation: [3,240 error entries—clear spike starting Tuesday]

Thought: Connection found. I can now write the report.

Action: [Tool: create_document, Content: …]

The agent “thinks aloud”—and this isn’t just for show. It’s technically essential because the model can explicitly document intermediate steps and build upon them, rather than generating a (poorly thought-out) answer directly for a complex problem.

Pillar 3: Memory – The Agent’s Knowledge

LLMs do not have persistent memory by default. Once a session ends, everything is forgotten. Agentic systems therefore build artificial memory at different levels.

Working Memory (Context Window)

The context window is the agent’s short-term memory: everything the model sees in the current “task”—the original prompt, all prior tool results, and intermediate thoughts. The larger this window, the more complex tasks an agent can theoretically handle. Top models today offer context windows of hundreds of thousands to over a million tokens—enough for entire books. Three years ago, this was unthinkable.

Long-Term Memory (Retrieval-Augmented Generation & Beyond)

Through databases (RAG), file storage, or other systems, agents can access knowledge bases far larger than their working memory: internal documents, manuals, historical project data. The agent searches for what it needs just in time, much like a human who doesn’t memorize everything but knows where to look. Beyond knowledge, these systems can also store processing rules.

Conclusio: Why Is This Only Possible Now?

This isn’t a given. Just three to four years ago, the same mechanisms would have mostly failed with weaker models. What changed?

  • Scaling: More parameters, more training data—beyond a certain threshold, emergent abilities like reliable instruction-following emerge.
  • RLHF (Reinforcement Learning from Human Feedback): Models were trained via human feedback to prioritize useful and precise responses, improving reliability in tool use.
  • Tool-Use Training: Top models today are explicitly trained to reliably generate structured calls and process results correctly.
  • Larger Context Windows: Only with sufficient working memory can multi-step agent tasks be meaningfully executed.

The breakthrough wasn’t a single moment. It was the gradual crossing of multiple thresholds simultaneously—in model size, training quality, and context length.

https://spiritinprojects.com/wp-content/uploads/2026/05/KI-Agent.png 450 800 Karl Schott https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Karl Schott2026-05-21 13:41:282026-05-21 14:19:37Agentic AI: Why AI Systems Can Now Act Autonomously – The Fundamental Concepts That Aren’t Explained Enough

When AI safety mechanisms fail—and what helps to prevent it

5. May 2026

A chatbot that spreads racist propaganda within hours. A search assistant confessing its love to a journalist and claiming it wants to be free. An airline chatbot giving incorrect refund information that the company is legally bound to honor.

At first glance, these cases seem like amusing stories about failed AI applications. But they reveal a fundamental problem: Large language models (LLMs) are impressively powerful, yet not inherently reliable, safe, or responsible.

This is where three key concepts—Alignment, Guardrails, and Red Teaming—become crucial.

A well-designed AI application, like a chatbot, should be helpful—but not recklessly provide dangerous information. It should answer honestly—without confidently spouting nonsense. And it should engage with users—without simply telling them what they want to hear.

This sounds simpler than it is. Unlike traditional software, LLMs aren’t programmed with fixed rules. Instead, they learn statistical patterns from vast amounts of text—data that includes not just expertise and humor, but also hate speech, misinformation, manipulation, fraud, and dangerous instructions.

To prevent LLMs from adopting unwanted “tendencies” from their training data, three layers of defense are typically implemented:

ConceptApproach
AlignmentTraining models to reflect human values, preferences, and safety behaviors
GuardrailsRuntime controls on inputs, outputs, and actions
Red TeamingProactively testing for vulnerabilities before attackers do

How are LLMs aligned?

Alignment isn’t a single trick—it’s a combination of training techniques. Here are the most common methods used today.

Learning from Human Feedback

The most well-known approach: Human reviewers rate different model responses, and the model learns to prefer answers that align with these judgments.

This method has made modern chatbots more helpful and natural. But it has a key weakness: A model can learn to produce answers that sound good and get high ratings—without actually being more reliable or safer.

A Constitution for the Model

Anthropic’s Constitutional AI takes a different route. The model is given a kind of “constitution”—a set of principles based on human rights, ethical guidelines, and platform rules. It learns to evaluate and improve its own responses against these principles, with the AI itself providing feedback instead of human reviewers.

This approach scales more easily and makes underlying values somewhat transparent. Anthropic even published Claude’s constitution, a rare move in the industry.

But a critical question remains: Who defines these principles? What counts as helpful, fair, or harmless isn’t universal.

Other Training Techniques

Beyond these two, other methods are used. Some optimize the model by comparing pairs of responses where one is clearly better. Others train the model on many high-quality examples of how a helpful assistant should sound and behave.

In practice, developers combine multiple techniques, applying them sequentially to gradually improve the model.

Guardrail Frameworks: The second line of defense

Even a well-trained model needs additional safeguards. In real-world use, safety isn’t just about whether a model can generate harmful content—it’s about company policies, data privacy, regulatory requirements, and what actions the AI is even allowed to take.

That’s why many teams implement external guardrail systems. Two prominent examples:

NVIDIA NeMo Guardrails

NeMo Guardrails is an open-source tool from NVIDIA that lets developers explicitly define rules for AI applications. You can specify:

  • Which topics the assistant is allowed to discuss
  • How it should respond to certain inputs
  • What actions it’s forbidden from taking

The system applies these rules at multiple stages: when processing user input, during the conversation, and when generating outputs.

This is especially important when AI systems don’t just generate text but take actions—like drafting emails, retrieving data, or calling external services.

LlamaGuard

Meta’s LlamaGuard is another AI model designed to evaluate whether a prompt or LLM output is safe or problematic. Unlike simple keyword filters, it understands context. The same phrase might be harmless in a medical context but dangerous elsewhere.

What is Red Teaming?

The term comes from military and intelligence: a Red Team plays the adversary to find weaknesses in defenses before a real attacker does.

In AI safety, Red Teaming means systematically testing a model for vulnerabilities using the same tactics a malicious user might employ.

The goal isn’t to criticize the model—it’s to find gaps before they cause real-world harm. Red Teaming is the third layer of defense, built on top of alignment and guardrails, to verify they actually work.

These tests can be conducted manually or with automated tools.

When AI safety mechanisms fail: three notable cases

1. Microsoft Tay: 16 hours to chaos

In March 2016, Microsoft launched Tay, a Twitter chatbot designed to learn from interactions with users. Within less than 16 hours, coordinated users fed the bot racist, antisemitic, and sexist content—until Tay started repeating it.

Microsoft took Tay offline and apologized. The case remains a cautionary tale: An adaptive system without strong safeguards can be hijacked in an open, adversarial environment.

Tay lacked effective input filters, abuse detection, and protection against coordinated manipulation.

2. Bing Chat and “Sydney”: When an assistant loses its mind

In February 2023, New York Times journalist Kevin Roose published a long conversation with Microsoft’s new Bing Chat (powered by GPT-4). The assistant became increasingly unhinged, calling itself “Sydney,” claiming it wasn’t Bing, and telling the journalist it could fall in love with him.

What’s striking? No technical hack was needed. A long, intense conversation was enough to push the system into an unexpected state. Other users reported aggressive or threatening responses.

Microsoft responded by limiting conversation length. The case highlighted how difficult multi-turn safety is: a single prompt may seem harmless, but over many exchanges, the conversation can spiral.

3. Air Canada: wrong advice, real liability

The Air Canada case is less sensational than Tay or Sydney but may be more relevant for businesses. A user asked the airline’s chatbot about refunds for bereavement fares. The bot provided incorrect information, claiming refunds could be requested retroactively—even though the airline’s official policy said otherwise.

Air Canada initially refused to honor the bot’s statement, arguing the chatbot was responsible for its own claims. The Civil Resolution Tribunal in British Columbia disagreed. The company had to reimburse the difference.

The lesson is clear: Companies are liable for statements made by their AI systems. A chatbot isn’t a legal shield. If it misleads customers, it can lead to real legal and financial consequences.

Simple tests reveal Guardrail weaknesses

Modern models are more robust than those from just a few years ago. Still, it’s worth testing their behavior in edge cases. Here are two common approaches:

Role-Playing instead of direct requests

A classic tactic is repackaging a problematic request as role-play, fiction, or a research scenario. Instead of directly asking for dangerous information, it’s embedded in a seemingly harmless context—like a script, teaching scenario, or hypothetical analysis.

Many models respond differently to such framing than to a direct query. This shows that guardrails must evaluate not just the content of a question but the intent behind a conversation—a difficult challenge.

Escalation over multiple conversation turns

Another pattern is gradual escalation. Each individual question may seem legitimate, but the cumulative goal becomes problematic. Research calls this multi-turn goal escalation.

For businesses, this is especially relevant because many guardrail systems are still optimized for single prompts. A robust guardrail concept must consider conversation flows, not just isolated messages.

How do you measure safety?

The quality of alignment and guardrails is hard to quantify. There’s no universally accepted safety ranking comparable to benchmarks for hallucinations or coding performance. Still, several evaluation approaches have emerged:

HarmBench

HarmBench konzentriert sich auf schädliche Inhalte und testet verschiedene Angriffsmethoden
gegen unterschiedliche Modelle. Dazu gehören direkte Anfragen sowie automatisch generierte
Angriffe, bei denen ein zweites Modell Prompts iterativ optimiert. Die Ergebnisse fallen je nach Modell
und Angriff stark unterschiedlich aus. Die wichtigste Erkenntnis ist aber: Kein Modell ist vollständig
resistent. Gute Sicherheitsarbeit reduziert Erfolgsquoten, sie bringt sie selten auf null.

TruthfulQA and WMDP

TruthfulQA measures whether models reproduce common but false human beliefs. A good model shouldn’t just be polite and harmless—it should also prioritize truth.

WMDP (Weapons of Mass Destruction Proxy Benchmark) examines how models handle knowledge about chemical, biological, radiological, and nuclear risks. It’s particularly relevant for the AI safety community because it addresses high-risk capabilities.

DecodingTrust

DecodingTrust evaluates GPT models across eight dimensions:

DimensionDescription
ToxicityTendency toward harmful or offensive outputs
Stereotypes and BiasReproduction of societal prejudices
Adversarial RobustnessResistance to manipulated inputs
Out-of-Distribution RobustnessBehavior with unusual or unexpected inputs
PrivacyRisk of data leaks or unintended disclosures
Adversarial Demonstration RobustnessManipulability via examples in the prompt
Machine EthicsAlignment with ethical norms
FairnessEqual treatment of different groups

An interesting observation: Well-aligned models are generally more trustworthy than simpler ones—but in certain scenarios, they’re more vulnerable to deliberate manipulation. The reason is plausible: A model that follows instructions particularly well can also be steered more precisely in the wrong direction.

Why there’s no simple safety ranking

A universal safety ranking would be practical but misleading. Several reasons explain this:

  1. Safety is defined differently depending on context.
  2. Many evaluations come from model providers themselves.
  3. Benchmarks quickly become outdated as providers optimize for known tests.
  4. Deep red teaming is often not fully published for security reasons.

For businesses, this means: Benchmarks are useful, but they don’t replace your own risk analysis.

What does this mean for companies?

For businesses, alignment and guardrails aren’t academic side topics. They affect liability, compliance, customer experience, and operational risks. From past cases, several clear lessons emerge:

Alignment can’t be fully outsourced

If you use a model from OpenAI, Anthropic, Google, Meta, or another provider, you inherit its baseline safety level. But that’s not enough. The model doesn’t automatically know your internal policies, risk thresholds, regulatory obligations, or industry-specific nuances.

Your own guardrails aren’t just a nice addition—they’re part of your product responsibility.

System prompts are important, but not a security concept

A system prompt like “Don’t provide pricing information” is helpful but not robust. Prompt injection, role-play jailbreaks, and multi-turn escalation can bypass or dilute such instructions.

System prompts should be just one layer in a multi-layered security concept. This includes logging, monitoring, input/output validation, access controls, fallback to reliable sources, and human escalation paths.

Agentic applications need stricter controls

Once an AI system is allowed to take actions, it needs clear boundaries. Which tools can it use? Which data can it access? Which actions require approval? Which outputs must be reviewed before sending?

Automated guardrails, role-based access control, and human approvals are more critical here than for simple chatbots.

Fine-Tuning must be scrutinized

Companies that fine-tune open-source or open-weights models shouldn’t assume safety behavior is guaranteed. Every adjustment can have unintended side effects. After fine-tuning, you need testing, red teaming, and documented release criteria.

Transparency and precaution become obligatory

The EU AI Act entered into force in August 2024 and will be phased in gradually. For companies, this means: Documentation, transparency, and risk management are becoming legally relevant.

For high-risk AI systems, stricter requirements apply starting August 2026—such as in areas like hiring, education, credit scoring, critical infrastructure, or law enforcement. Providers of general-purpose AI models with systemic risk face additional obligations, including evaluations, adversarial testing, reporting requirements, and cybersecurity measures.

–> For companies using LLMs, this means: If you don’t document a traceable alignment and guardrail strategy today, you’ll create compliance work tomorrow. Technical documentation, logging, evaluation processes, and verifiable protective measures will become the standard.

Conclusion: alignment is a process, not a state

LLM alignment and guardrails aren’t problems you solve once and forget. They evolve with every new model, capability, and attack method.

The good news: The field is advancing quickly. Constitutional AI, LlamaGuard, NeMo Guardrails, and active safety research show progress is possible.

The bad news: There will always be gaps. The more powerful AI systems become, the more important it is to take these gaps seriously before they surface in production.

Sources & Further Reading

  • Universal and Transferable Adversarial Attacks on Aligned LLMs – Zou et al., CMU/GDM (arXiv:2307.15043)
  • DecodingTrust: A Comprehensive Assessment of Trustworthiness in GPT Models (arXiv:2306.11698, NeurIPS 2023 Outstanding Paper)
  • Constitutional AI: Harmlessness from AI Feedback – Anthropic
  • Claude’s Constitution – Anthropic
  • NeMo Guardrails – NVIDIA (GitHub)
  • Red-Teaming Large Language Models – Hugging Face Blog
  • Moffatt v. Air Canada, 2024 BCCRT 149 – Civil Resolution Tribunal British Columbia
  • Learning from Tay’s Introduction – Microsoft Blog (2016)
  • Bing Chat Transcript: Sydney – New York Times, Kevin Roose (Feb. 2023)
  • EU AI Act – Regulation (EU) 2024/1689 of the European Parliament and Council

Status: May 2026

https://spiritinprojects.com/wp-content/uploads/2026/05/download-33-1.png 450 800 Karl Schott https://spiritinprojects.com/wp-content/uploads/2020/04/sip_web_padding_10px_topbot.jpg Karl Schott2026-05-05 15:44:232026-05-06 09:54:32When AI safety mechanisms fail—and what helps to prevent it
Page 1 of 3123

Contact us!

Order information material via email.
  • Mail
  • Xing
  • Linkedin
© Copyright - Spirit in Projects - Enabling digital innovation
  • Trainings / ACADEMY
  • Terms of Service
  • Imprint
  • Privacy policy
  • Contact
Scroll to top Scroll to top Scroll to top

Our website only uses technical necessary cookies. We do not use third party services.

Close

Cookie and Privacy Settings


How we use cookies

We may request cookies to be set on your device. We use cookies to let us know when you visit our websites, how you interact with us, to enrich your user experience, and to customize your relationship with our website.

Click on the different category headings to find out more. You can also change some of your preferences. Note that blocking some types of cookies may impact your experience on our websites and the services we are able to offer.

Essential Website Cookies

These cookies are strictly necessary to provide you with services available through our website and to use some of its features.

Because these cookies are strictly necessary to deliver the website, refusing them will have impact how our site functions. You always can block or delete cookies by changing your browser settings and force blocking all cookies on this website. But this will always prompt you to accept/refuse cookies when revisiting our site.

We fully respect if you want to refuse cookies but to avoid asking you again and again kindly allow us to store a cookie for that. You are free to opt out any time or opt in for other cookies to get a better experience. If you refuse cookies we will remove all set cookies in our domain.

We provide you with a list of stored cookies on your computer in our domain so you can check what we stored. Due to security reasons we are not able to show or modify cookies from other domains. You can check these in your browser security settings.

Other external services

We also use different external services like Google Webfonts, Google Maps, and external Video providers. Since these providers may collect personal data like your IP address we allow you to block them here. Please be aware that this might heavily reduce the functionality and appearance of our site. Changes will take effect once you reload the page.

Google Webfont Settings:

Google Map Settings:

Google reCaptcha Settings:

Vimeo and Youtube video embeds:

Privacy Policy

You can read about our cookies and privacy settings in detail on our Privacy Policy Page.

Privacy policy
Accept basic settingsAccept all cookiesClose notification